How to Analyze Your Process and Find a Process Bottleneck
ProcessMind's six-step method for reading your dashboards, exploring the flow and finding a process bottleneck you can defend with evidence.

This guide is written by ProcessMind, for people who analyze processes in ProcessMind. The method is general enough to reuse in any tool, but every step names the screen in your workspace that does the work, so you can follow it with your own data instead of translating an abstract checklist. Data alone does not tell you which result matters. The six steps take you from the dashboards you already have to a process bottleneck you can defend with evidence.
That is why the guide serves two readers. Some people arrive already knowing how to read a process and only want the ProcessMind equivalent of each move: which view, which metric, which filter. Others are new to analyzing business processes and need the reasoning first, so that nothing happens in the tool they cannot explain. Both routes are here, in the same order.
You do not need a data engineering project to start. An export you already have is enough: one row per event, with a case identifier, an activity name and a timestamp. Everything below runs on a dataset in ProcessMind, and nothing below asks you to connect a live system first.
At first we assumed that an easy-to-use tool was all anybody needed. Then we saw the split: some people read a process naturally, and others need a method before the numbers mean anything. So we wrote one guide for both. If you already know how to analyze a process, you will find practical things to do and how to do them in ProcessMind. If you do not, it gets you started. Either way, keep one question in front of you: what do I see, what does it mean, and how can I use it to improve the process?
The rest of the guide follows that question. Seeing is the dashboards and the Process Graph. Meaning is the timing, the variants and the cases behind them. Improvement is the decision you take afterwards, and the way you check whether it worked.
What you need before you start
An analysis starts before the first chart. ProcessMind can only answer questions the data can carry, so spend two minutes on the inputs.
Before you open a dashboard
- A dataset with a case identifier, an activity name and a timestamp per event
- One process and one time range you can explain to a colleague
- The dashboards that ship with the dataset, opened at least once
- One person who knows how the work is really done, to check your reading
If the dataset is not in the workspace yet, upload your event log and then configure the dataset so ProcessMind reads your case identifier, activity name and timestamp correctly. Attributes such as cost, resource and rework status are optional, but the columns you leave out are the questions you cannot ask later, so check dataset attributes before you begin. When a field you need is missing from the export, calculated attributes can derive it from the columns you have.
The gap between your dashboards and a defensible finding
ProcessMind reconstructs a process from event data and calculates the metrics. It will show you that one activity carries the longest waiting time, that a single variant holds a third of the cases, or that rework appears in one case in five. It will not decide which of those results matters, explain why the pattern exists, or tell you what to change. That is the work this guide is about.
Most teams already have dashboards. The difficulty is turning them into an explanation of how work really runs. A documented process describes an intended route, while the event data shows the routes cases actually take, and ProcessMind holds both: the model you draw or generate, and the dataset that reports against it. Comparing the two is where process bottleneck identification starts.
Treat a difference between the data and your expectations as a question, not a verdict. Work changes, exceptions accumulate, and no system records everything. The comparison tells you where a bottleneck is worth investigating, and occasionally that your own picture of the process was out of date.
The six steps of a ProcessMind analysis
Each step answers one question and hands a smaller question to the next. The view names are the ones you will see in the workspace. Run in order, the six steps are a process bottleneck framework you can reuse on the next dataset.
-
Understand your dashboards
Read what each ProcessMind chart measures, then open the Process Graph with the same period and filters. -
Explore the process
Watch the flow in Process Animation, filter one thing at a time, and compare Process Variants. -
Focus your analysis
Turn what you saw into three to five questions your data can answer. -
Deep dive with the right view
Test each question in the Process Graph, Process Variants and the Case Explorer, and bookmark the evidence. -
Summarize your findings
Connect every finding to a view, a filter and a number, and keep observation apart from interpretation. -
Decide what comes next
Assign the follow-up, simulate the change, and set up how you will monitor it.
Step 1: Understand your dashboards
Before investigating a pattern, make sure you know what each chart measures. A dashboard that looks clear can still hide its period, its population or its calculation, and the Process Graph inherits the same filters when you open it.
Read each chart on its own terms
ProcessMind groups its charts by the question they answer: time and volume, rework, conformance, and process health. Open the dashboard that fits the question you arrived with, then read each chart the same way you would read a report:
- What does it measure? Throughput time, processing time, waiting time, case count, or another metric?
- What do the values represent? Hours, days, percentages, or counts?
- Which cases are included? Check the filters and the dataset behind the chart.
- What time period does it cover? A month, a quarter, or everything in the dataset?
- How is the value summarized? An average can hide cases that are much faster or much slower.
Check the chart settings instead of relying on memory. When a value is an average, compare it with the distribution behind it: one unusually long case can pull an average upward and make a healthy process look slow.
Check the metric definitions you will use
ProcessMind separates the three time metrics for a reason: throughput time, processing time and waiting time count different things, per case and per activity. If you treat them as interchangeable, the bottleneck you find can be an artifact of a definition. Read what each time metric counts before you compare them.
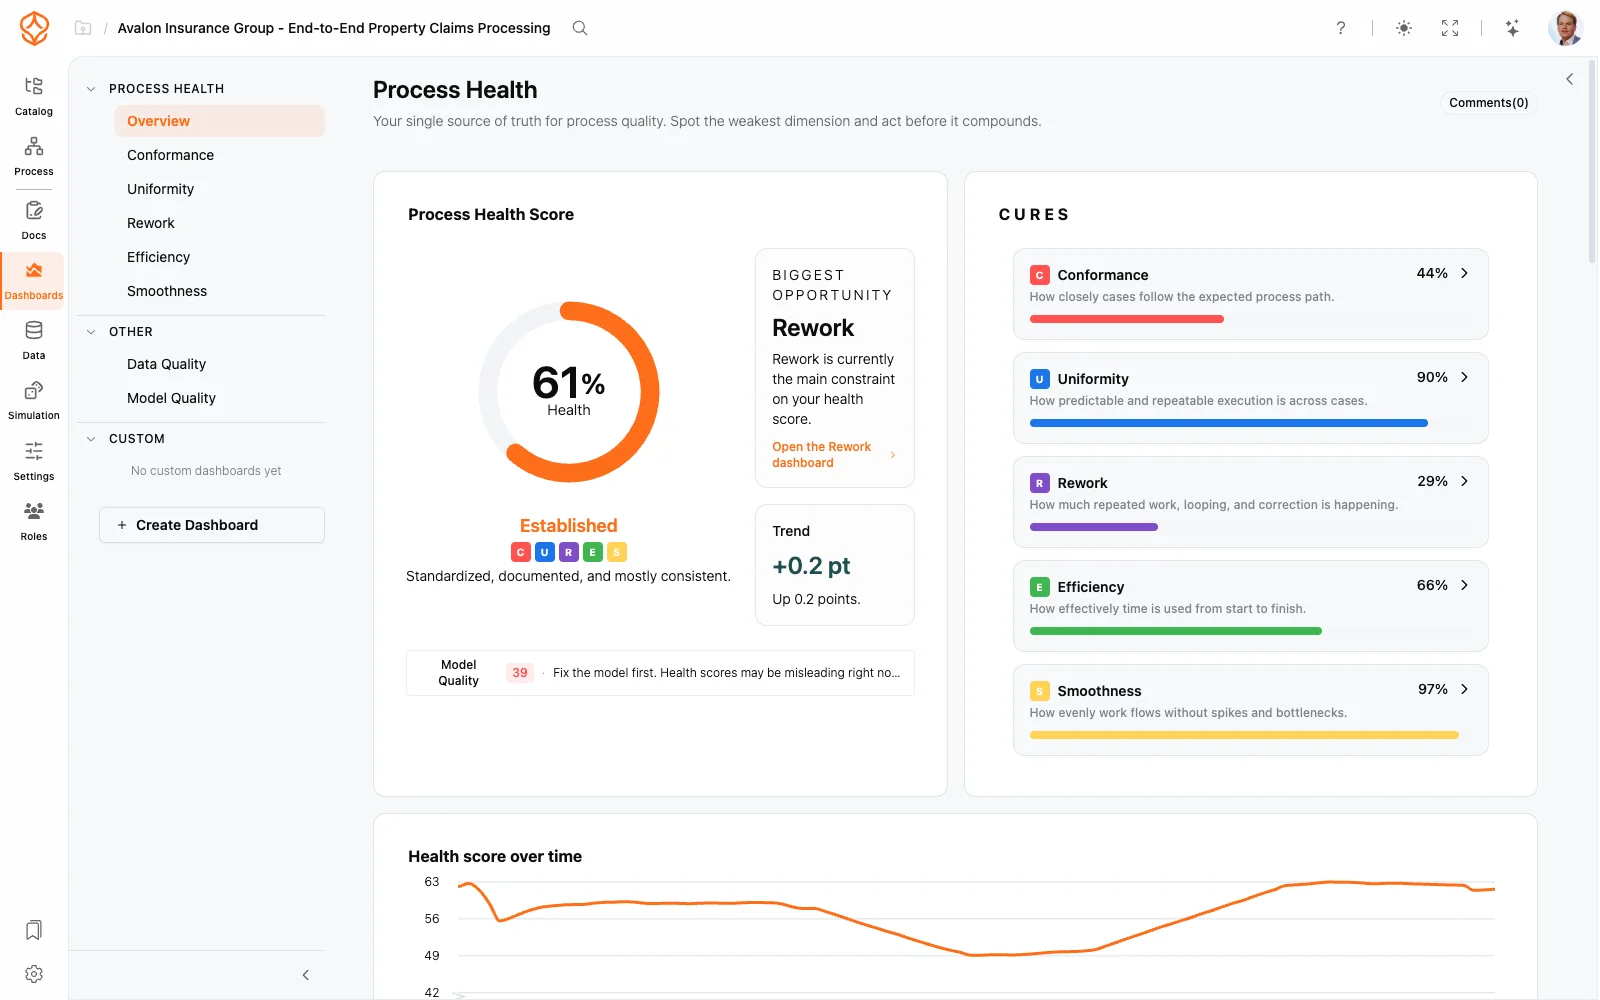
For a first pass over the whole process, open the Process Health dashboard. It scores the process across the five CURES dimensions, Conformance, Uniformity, Rework, Efficiency and Smoothness, and names the weakest one first. That turns “where do I start?” into a ranked question.
Read the numbers against the process you know
Ask whether you can explain a result with what you know about the work. If the dashboard shows an average throughput time of five days for order processing, does that fit how the work is handled? If the Process Graph shows many cases taking an unexpected route, do you know what causes that route?
A mismatch is a useful starting point. It can be a genuine process issue, a difference in how teams work, an incomplete event log, or a metric you have read incorrectly. Write down what you know and what still needs checking.
Look at the cases behind a number
When a chart raises a question, open the Case Explorer and inspect individual cases. Choose cases that illustrate the pattern, then read their events from start to finish.
Look for:
- The activities recorded for each case
- The order in which they happened
- Long gaps between events
- Repeated activities or unexpected routes
- Differences between cases that look similar on the dashboard
Compare the recorded sequence with your understanding of the process. A step may be missing from the system, or an activity name may mean something else in practice. An individual case explains a pattern; check more than one before you conclude anything.
Write down what you know
Keep a short record of:
- What each dashboard and chart measures
- Which filters and time period are active
- Known data limitations
- Your reading of the main metrics
- Questions that need follow-up
That record is what you compare the next run against, and what a colleague reads to check your reasoning.
Step 2: Explore the process
Once you know what the dashboards measure, explore the process without trying to prove a particular explanation. Look for patterns that deserve a closer look, then use filters and Process Variants to see whether they hold across different groups of cases.
Start with Process Animation
Process Animation plays the cases through the Process Graph over time. Set the period and the filters first, then watch the flow: cases move between activities and stack up where they wait.
Look for:
- Activities where cases build up
- Loops where cases return to an earlier activity
- Routes that many cases follow, and routes only a few take
- Differences in flow between groups of cases
Animation shows you a pattern; it does not explain it. Use it to choose what to investigate next, then confirm what you saw against the metrics and the cases.
Filter one thing at a time
Use filters to narrow the dataset and compare groups, for example:
- This month against the previous quarter
- One customer or case type against another
- Cases that ended successfully against cases with delays
- Cases on the standard route against cases that deviated
Change one filter at a time where you can. That keeps the difference attributable to the thing you changed, and it keeps the comparison reproducible when somebody asks how you got the number.
Break the process down by dimension
ProcessMind splits the process by the attributes in your dataset:
- Department, team or resource
- Region or location
- Product or service category
- Customer segment
A process that looks consistent overall often behaves differently across teams or case types. A difference between groups is a lead, not proof that one team performs worse: check whether the groups handle comparable work and whether the data captures their activities the same way.
Compare variants, not the average
Process Variants lists the distinct routes cases take and how often each one occurs. Ask:
- Which route do most cases follow?
- Which deviations are frequent rather than exceptional?
- How do throughput time and other metrics differ across routes?
- Are the rare routes genuine exceptions, or a recurring workaround?
A handful of variants usually carries most of the cases, and a long tail carries the exceptions. Start with the routes that affect the most cases, but check a rare route if its cases are expensive or slow: frequency alone does not set priority.
Write your explanations as hypotheses
As you explore, put the possible explanations into plain language:
- “Cases from this region take longer because they need an extra approval.”
- “Cases with this attribute wait before the next activity.”
- “When this step repeats, the case takes longer to finish.”
Each sentence is a hypothesis. Ask what evidence would support it and what would contradict it, then test it with filters, Process Variants and the Case Explorer. A plausible story is not a finding until the data agrees.
Step 3: Focus your analysis
Exploration produces more questions than one investigation can answer. Choose the questions that matter most to the process owner and that your dataset can actually answer.
Find the recurring themes
Read back through your notes from the first two steps:
- Which patterns appeared more than once?
- What surprised you?
- Which results still need an explanation?
- Which questions matter to the people responsible for the process?
- Where do process experts already see a problem or an opportunity?
Combine what the data shows with what people know about the work. Neither source is complete alone: the data gives you frequency and timing, and the process owner explains the policies, exceptions and changes that never reach the event log.
What does a good analysis question look like?
Write questions you can answer with the dataset in front of you, and turn a vague ambition into a measurable pattern.
- Why is throughput time higher for some case types?
- Which activities or handoffs account for the most waiting time?
- Why do some cases leave the most common variant?
- What separates the fastest cases from the slowest?
- Where do cases repeat an activity, and how much time sits in those cases?
“How can we make the process better?” is not a question the data can answer. It becomes one when you name the pattern, the group of cases and the outcome you want to explain.
Prioritize three to five questions
Choose three to five questions to investigate first. For each one, check:
- Is it specific and actionable? Name the process area, the case group or the measure.
- Can this dataset answer it? List the fields and the views you will need.
- Does the answer matter? Weigh how many cases are affected and what the result could change.
- Can you validate the reading? Name the process owner or expert who can check it.
A focused analysis is easier to finish and easier to explain. The rest of your questions wait for another round.
Set expectations
Analysis is iterative. Stakeholders may say they already knew about a pattern, which still gives you evidence for a decision. They may also ask what caused it. If you cannot answer that yet, name the next question instead of overstating the result.
Stay with your priority questions, and put interesting side findings on a follow-up list so they do not take over the investigation. You can run another cycle later; answering the most important questions first gives stakeholders something to decide on.
Step 4: Deep dive with the right view
For each priority question, pick the view that fits it. Start with the whole process, narrow the dataset to the cases you need, compare the groups you named, and open individual cases where the pattern needs explaining.
Match the question to the view
| Question | ProcessMind view |
|---|---|
| Where does the time go? | Process Graph with a time metric selected |
| Where do cases wait? | Process Animation and the waiting-time chart |
| Which routes do cases take? | Process Variants and path filters |
| Why does this case behave differently? | Case Explorer |
| How does work vary by team or resource? | organizational selectors and the resource charts |
| What would this change do to the process? | simulation on the model |
Work through the evidence
For each question:
-
Start with the whole process
Check the pattern across all cases before you narrow anything. -
Apply filters
Isolate the period, the case type or the outcome you want to understand. -
Compare the groups
Look for the difference between the cases you named in the question. -
Inspect examples
Open the cases behind the pattern in the Case Explorer. -
Check consistency
Confirm the pattern holds across enough cases to carry your conclusion.
Keep the question in front of you while you work. A chart can reveal an interesting pattern that does not answer the question you set out to investigate, and that belongs on the follow-up list.
Record findings as you go
For each useful result, write down:
- The question you were investigating
- The view and the metric you used
- The filters and the time period
- What the data shows
- What you think it means
- What still needs validation
Save the view itself with Process Bookmarks. A bookmark restores the same filters and settings, so you can answer a follow-up question in the review without rebuilding the analysis.
Clear or isolate blocking data issues
If a data issue stops you answering a priority question, decide whether you can fix it or should narrow the question. Missing timestamps make a time comparison unreliable, and no amount of analysis repairs that. ProcessMind lists the underlying problems on the Data Quality dashboard.
If the issue does not affect the question, note it and continue. Repairing every data limitation before finishing any analysis delays the finding without improving the answer you need now.
Finding a process bottleneck: six techniques
A process bottleneck is a constraint that limits how quickly work can move through a process. Process bottleneck analysis finds where cases wait, which patterns sit alongside the delay, and what still needs validating. Six techniques cover most of the ground, and each one has a ProcessMind surface that answers it.
A long activity time on its own does not prove that the activity is the constraint. Check the queue in front of it, the flow into and out of it, and the cases affected before you name it. The Process Graph is also the process bottleneck visual you can put in front of a process owner, because it carries the numbers and the route in the same picture.
Cycle time: where does the time go?
Question: How long do cases take, and where is that time spent?
Where in ProcessMind: the Process Graph with a time metric selected, and the time distribution behind it.
- Select Average Throughput Time or Average Processing Time on the Process Graph, with the same period and filters as the dashboard you came from.
- Read the values on the activities and the connections: work shows on the activity, waiting shows on the connection between two activities.
- Compare the longest connections with the overall throughput time. A few connections usually carry most of the total.
- Switch between the average and the distribution. A small group of long cases can move the average on its own.
- Open the cases behind the longest connection in the Case Explorer.
Look for:
- Connections with unexpectedly high waiting time
- Long gaps between activities
- Differences in throughput time by case type, region or another dimension
- A large gap between the average and the distribution
Watch out: a long throughput time is not proof that the work is slow. A case can sit for days waiting for the next step. Find where the time sits before you name an activity as the constraint.
Rework: where do cases repeat a step?
Question: Where do cases repeat activities, and how often does that happen?
Where in ProcessMind: the Process Graph, the rework dashboard, Process Animation and Process Variants.
- Look for backward connections in the Process Graph: they are the repeat loops.
- Read the rework charts to see which activities are revisited most and what share of cases carries the repetition.
- Play the flow in Process Animation to watch cases return to an earlier activity.
- Filter for the cases that contain a repeated activity, then compare their throughput time with the cases that do not.
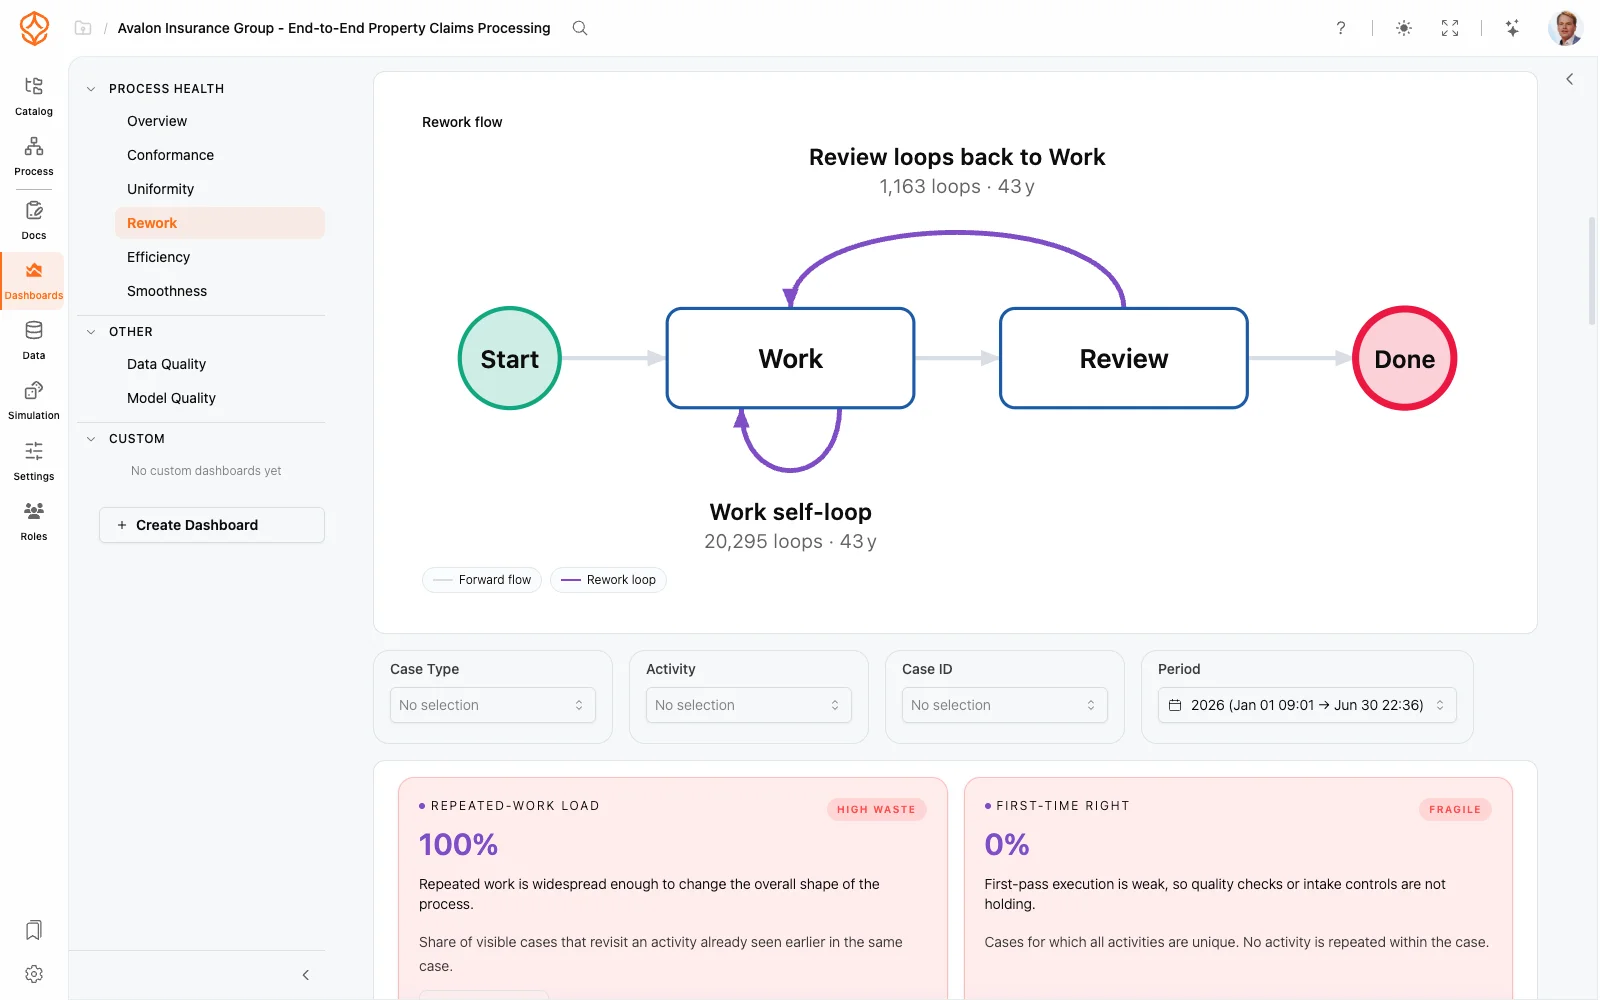
Look for:
- Activities that cases visit more than once
- Repeated sequences such as Review, Correct, Review
- The share of cases that include rework
- The throughput-time difference between cases with and without the repetition
Watch out: some repetition is a valid control. Frequent rework can point to unclear requirements, quality problems or handoff issues, but the event data shows the pattern and not the cause. Check it with the people who do the work.
Conformance: where does the flow leave the model?
Question: How often does the actual flow differ from the modeled process?
Where in ProcessMind: the conformance dashboard, the Process Graph and the conformance filters.
- Agree with the process owner on the required activities and the expected route, because the model is the reference the check runs against.
- Open the conformance dashboard and read the deviations it reports.
- Apply the conformance filters to see which activities are skipped, added or repeated.
- Compare the deviating routes in Process Variants, and how often each one occurs.
- Check whether each deviation is a permitted exception or a workaround nobody wrote down.
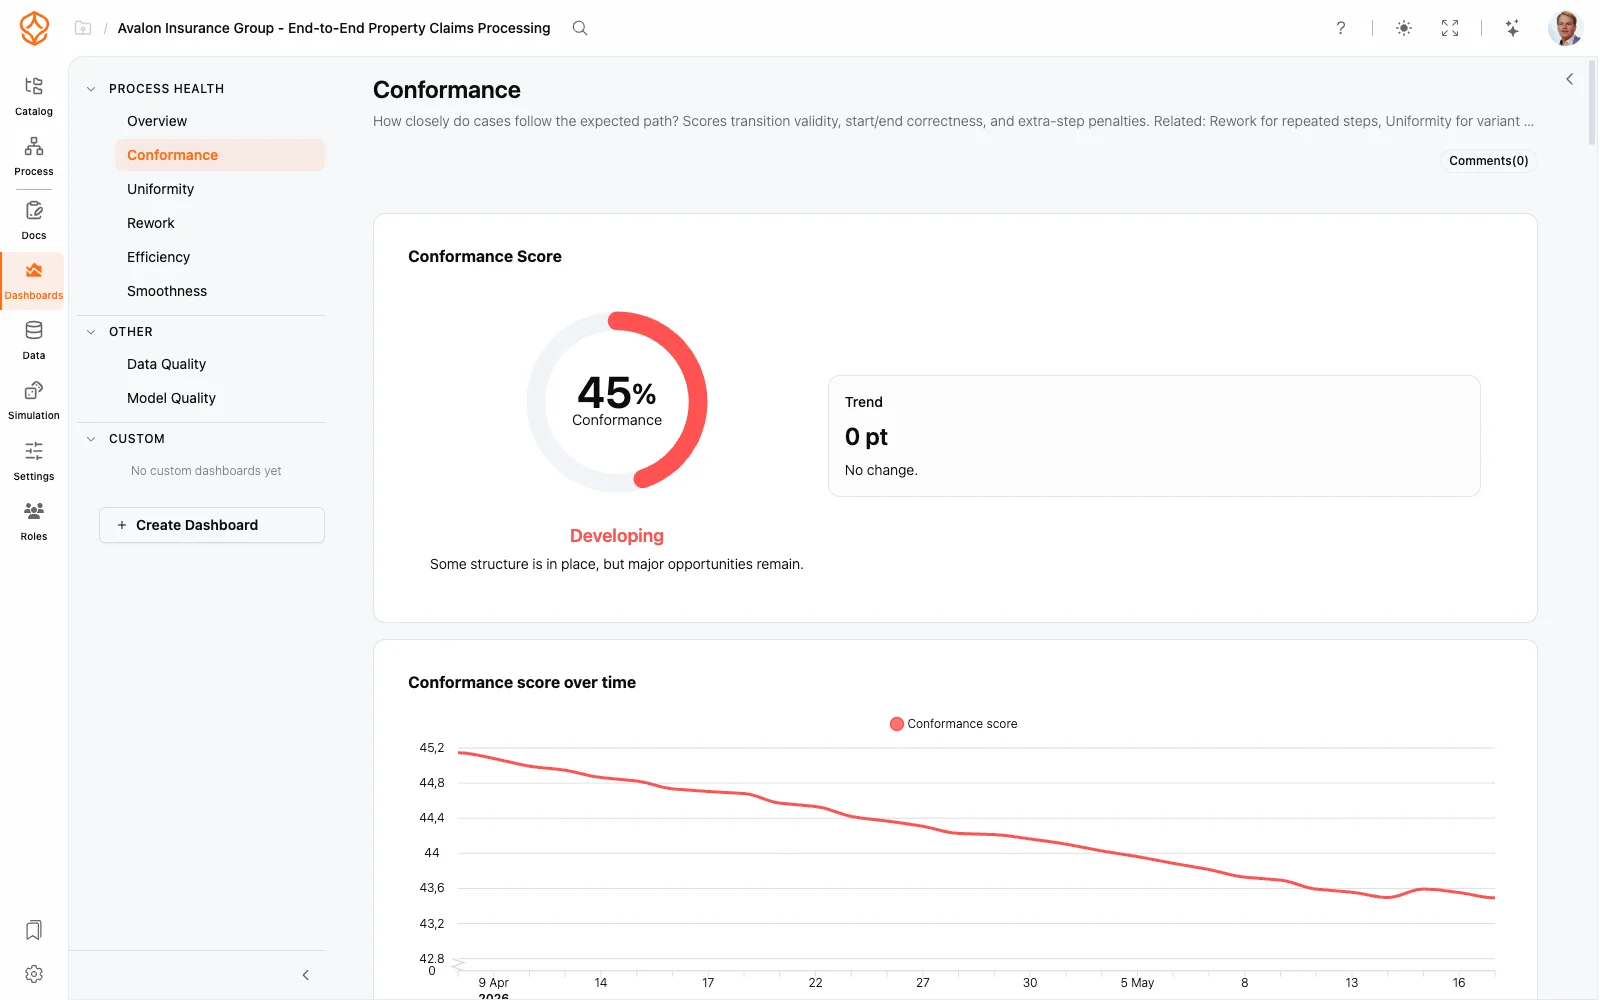
Look for:
- Activities that should happen but are missing
- Activities that appear unexpectedly
- Routes that differ from the model
- Cases that end before the expected end event
Watch out: a deviation is not automatically a problem. It can be an approved exception, or a practical workaround that deserves documenting instead. Confirm the intended process with its owner before you call a variation non-conformance.
Resource: how is the work spread across teams?
Question: How is work distributed across resources, teams or departments?
Where in ProcessMind: the organizational selectors, the resource chart and the filters.
- Break the process down by resource, team or department, using the organizational attributes in the dataset.
- Compare case volumes and throughput times across the groups.
- Look at the handoffs between groups: every handoff is a place where waiting time enters the process.
- Check whether the groups handle comparable cases and whether the data captures their work the same way.
Look for:
- Uneven workload across teams or resources
- Throughput time that differs between teams
- Repeated handoffs between departments
- Activities that depend on a small number of people
Watch out: a difference between resources does not show that one person or team performs better. The work may differ in complexity, training, tools or how it is recorded. Use the comparison to write better questions for the process owner, never to judge individuals.
Volume and trend: when does the process change?
Question: How does case volume change over time, and does performance change with it?
Where in ProcessMind: the period filters and the trend charts.
- Compare defined periods with the same filters and the same metric.
- Read whether volume is rising, falling or stable across the dataset.
- Compare a period with the same period a year earlier, where the data reaches back that far.
- Check whether the changes in volume line up with changes in throughput time or another KPI.
Look for:
- Seasonal patterns in volume
- Trends that coincide with a known business event
- Throughput time that moves when volume moves
- Differences between periods you expected to be comparable
Watch out: a performance change that coincides with a volume change does not prove that volume caused it. Look for other changes, and check the timing with the people who ran the operation.
Path and variant: which route does the work take?
Question: Which routes do cases take, and how do those routes differ?
Where in ProcessMind: the Process Graph, Process Variants and the path filters.
- Use the Process Graph to find the decision points and the alternative routes leading out of them.
- Read how many cases take each route in Process Variants.
- Filter to one variant and compare its throughput time and outcome with the others.
- Check the routes the process owner expects, and the routes they do not.
Look for:
- The common route, and the exceptions around it
- Throughput time that differs between variants
- Routes with extra steps or repeats
- A route the process owner wants reviewed
Watch out: start with the variants that carry the most cases, then weigh a rare route by what its cases cost. Frequency alone does not set priority; the consequence of the route does.
Step 5: Summarize your findings
The analysis is useful when the people responsible for the process can follow what you found and decide what to do next. Present the question, the evidence, and the limits of your conclusion, in that order.
Structure each finding
For each priority question, write the same five lines:
- Question: What did you investigate?
- Finding: What does the data show?
- Evidence: Which view, metric, filters and cases support it?
- Implication: What could this mean for the process?
- Next step: What should the process owner validate or decide?
Separate what the data shows from your reading of it. “Cases in this group have a longer average throughput time” is an observation. “The approval step causes the delay” is a causal claim that needs more evidence, and usually a simulation or a change to prove it.
Build a presentation stakeholders can follow
Organize the review so the reasoning is visible:
- Summary: The main findings and the decisions you need
- Method: The dataset, the period and the approach
- Findings: One section per priority question
- Implications: What the findings could mean for the process
- Next steps: What to validate, what to consider, and who owns it
- Supporting detail: The charts, filters and case examples
Present from ProcessMind when the discussion allows it, so the audience sees the filters next to the numbers and can ask for a different cut live. When you export charts into a deck, keep the period and the filter in the caption, because a chart without them cannot be checked. Process Charts covers the export options, and Custom Dashboards lets you build the view a specific meeting needs.
Size the impact carefully
Translate the finding into business terms where the data supports it: a group of cases with a longer throughput time, a defined share of cases with rework, a variant that carries a third of the volume.
Be precise about what you measured. Do not present a possible improvement as a guaranteed result. If you estimate the effect of a change, state the assumption and label the estimate as an estimate. A simulation is the honest way to show what a change might do, because it models the change on the process instead of extrapolating from one chart.
Get feedback before you present
Review your findings with:
- A colleague who understands the data
- A process expert who knows how the work is done
- A stakeholder who can check whether your reading fits the operation
Ask them to challenge the assumptions and supply the missing context. The review catches data issues, and it is the cheapest place to stop a correlation from being presented as a cause.
Step 6: What comes next
After you share the findings, agree on what happens next. Some results lead to a process change, others need more investigation or a better dataset. Record the decision and who follows up.
Track the action items
A review produces requests for more analysis, decisions about possible improvements, or assignments for process owners. Capture each item with an owner and a next step, or it disappears into the day-to-day work.
Simulate the change before you commit
Analysis supports a decision; it does not implement the change. In ProcessMind the natural next step is to test the change on the model: What-if analysis compares an as-is and a to-be scenario with the same data, so you can see the effect on throughput time before anybody rebuilds a process. The simulation capability page describes what the engine does. For the wider move from finding to business improvement, read how to implement process optimization.
Monitor whether the change worked
If the process changes, compare the periods before and after with the same definitions and the same filters. Check whether the intended metric moved, and whether anything else moved with it. Process Health is built for that comparison, and how to continuously monitor your process is the method behind it.
Document the analysis
Keep a record of:
- The questions you investigated
- The dataset and the period you used
- The data limitations that mattered
- The findings and the evidence behind them
- The decisions, the owners and the follow-up
That record is what makes the next analysis faster, and what lets somebody else check your reasoning.
Repeat the cycle
Process analysis is not a one-off. New data, changed work and new questions all start another round, and every round is a chance to turn a finding into business improvement or business optimisation. Keep the question list short, keep the evidence with the finding, and the method gets quicker every time.
Get started with ProcessMind
You can run this method on an export you already have. ProcessMind reads it into a dataset, draws the process, and gives you the dashboards, the Process Graph and the Case Explorer that the steps above rely on, then lets you save the views with bookmarks and share them with the people who own the process.
To put it together the first time, follow the getting started guide. No connector is needed for the steps described here.
If you want the essentials of the flow itself, read What is Process Mining? for how event data becomes a process. A Strategic Guide for Data-Driven Process Improvement is the wider programme this analysis feeds, and Process Improvement Techniques: The Ultimate List compares the methods around it.
Where to Go From Here
You have the method and a short list of questions. The next step is to run it on your own data, then decide what to change and how you will check whether it worked.