Event Log Process Mining: How to Build One
Build a process mining event log with the right columns, a downloadable restaurant example, and step-by-step Excel and SQL methods.

Event log process mining starts with one table: timestamped activities, grouped by case ID. This guide builds that table from system data, using a fictional restaurant order process, and it gives you both routes: a few rows in Excel, or one SQL query that stacks the activities with UNION ALL. Compare your work with the finished example log as you go.
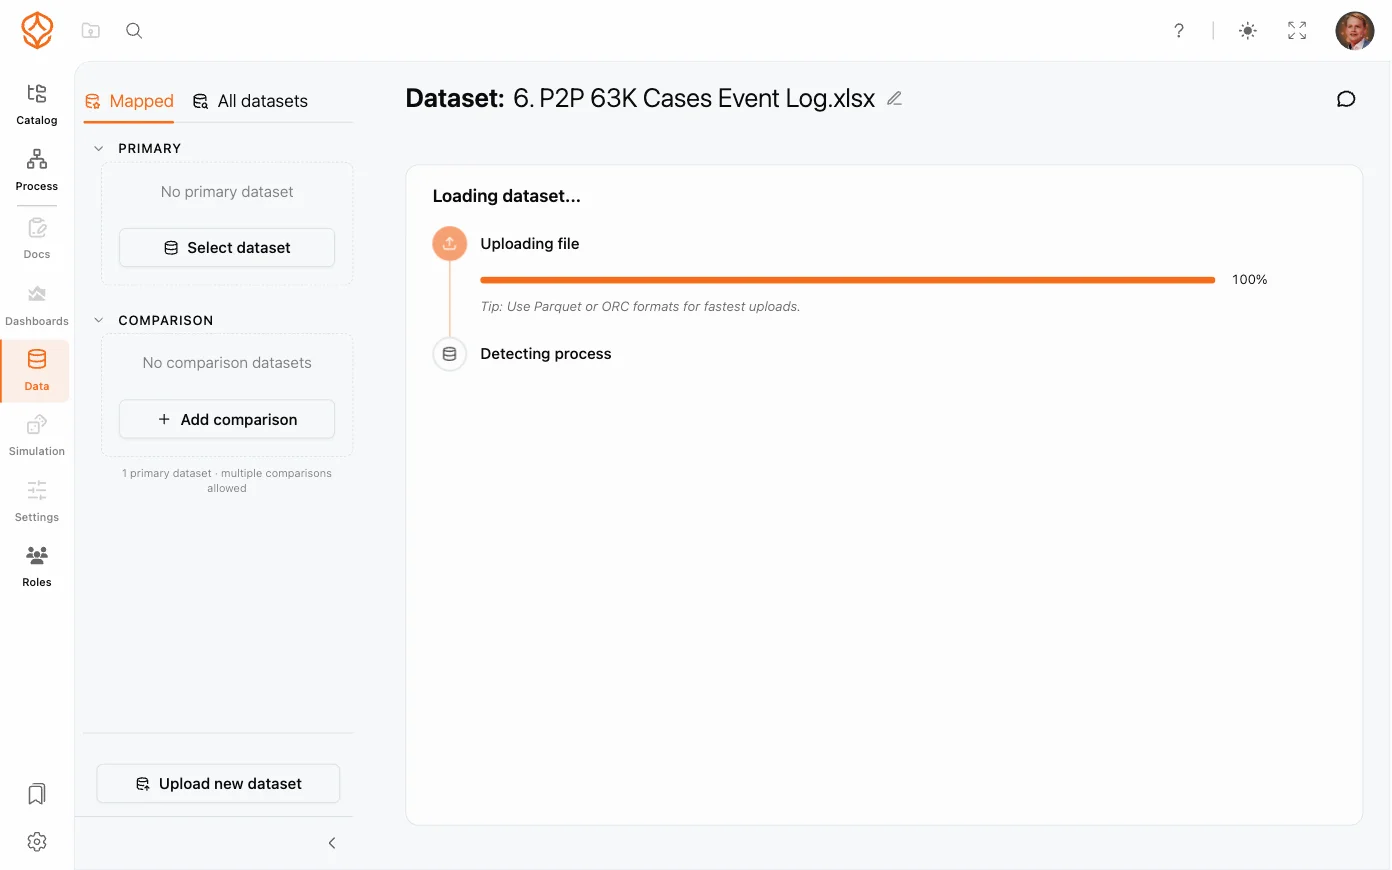
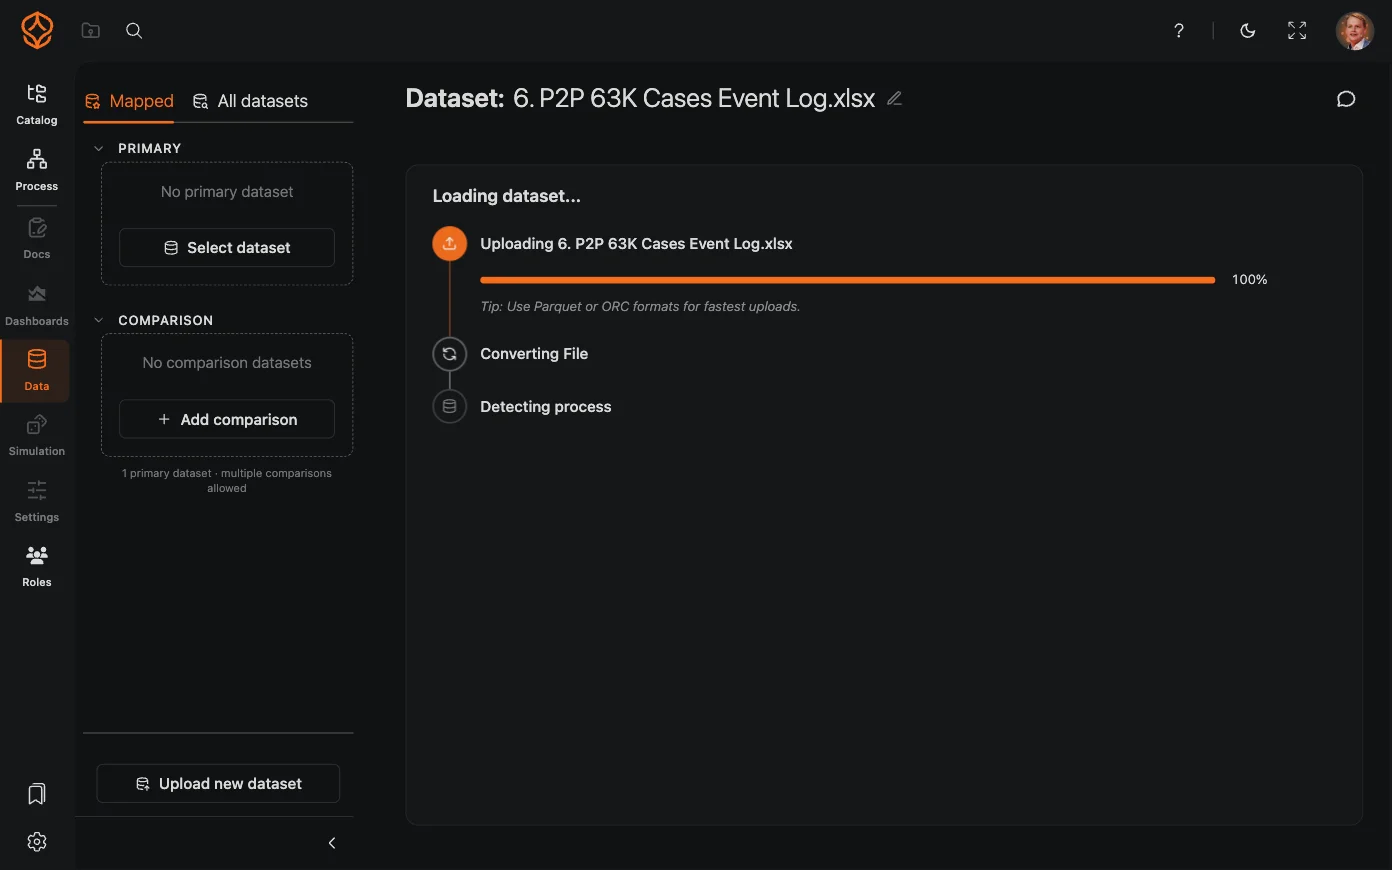
Creating an event log has a reputation as a daunting task. It is not, as long as you do not try to do everything at once. Start today with a template, or with a handful of rows in Excel, and scale up once you understand what you need.
Event log process mining: the three columns you need
An event log is a structured record of what happened in a process. Each row is one event, such as an order being placed or a payment being received. A case ID connects related events, a timestamp places each event in time, and together they let a tool reconstruct how cases move through the process.
An activity is a type, an event is an occurrence. An activity is a kind of action, such as “Order Shipped.” An event is one specific happening of it: order 12345 shipped at 2:30 p.m. on January 15. Your log records events, and every event carries an activity name. People use the two words interchangeably, but the distinction matters when you prepare data, because the activity says what happened while the event says it happened to this case at this time.
A basic process mining event log needs three columns:
| Column | What it contains | Example |
|---|---|---|
| Case ID | The identifier that groups events belonging to the same case | 1001 |
| Timestamp | When the event occurred | 2025-01-15 18:30:00 |
| Activity | What happened | Order Placed |
Then check the three fields before you go further:
| Check | What to confirm |
|---|---|
| Case ID | Related events share the same ID; different cases have different IDs |
| Timestamp | Each event has a usable date and time |
| Activity | Names are clear and consistent across the extract |
These three fields are the foundation, and if one is missing or inconsistent the process view will misrepresent the sequence of work. Everything else is optional: an event log business process mining tools can read is always one table of cases and events, and the three columns that make a business process mining event log usable never change. For supported formats and preparation steps, see the process mining data documentation.
A worked example: the Pizza Palace order system
To make the steps concrete, we’ll use a fictional restaurant called Pizza Palace. Customers place orders online, staff prepare the food, and drivers deliver it. The example contains no customer data.
Imagine the system stores information in these tables:
- orders: order ID, customer, and order time
- order_items: pizzas, sides, and drinks in each order
- kitchen_queue: when an order enters and leaves the kitchen
- delivery_assignments: driver assignments and delivery tracking
- payments: payment processing records
The goal is to create one event log that follows each order from placement through delivery. The order ID will be the case ID. Each relevant timestamp and action will become a row. Download the Pizza Palace example log as a sample event log for process mining, and compare its columns with your own extract.
Decide which activities to include before you extract. For Pizza Palace, the order journey has six steps:
- Order Placed: The customer submits the order.
- Payment Received: The payment is processed successfully.
- Order Sent to Kitchen: The order enters the preparation queue.
- Order Ready: The kitchen marks the order complete.
- Assigned to Driver: A driver is assigned.
- Delivery Completed: The order is delivered.
For each activity, identify its source table, timestamp field, and case ID field. Confirm that the case ID links the event to the right order.
| Activity | Source table | Timestamp field | Case ID field |
|---|---|---|---|
| Order Placed | orders | created_at | id |
| Payment Received | payments | payment_time | order_id |
| Order Sent to Kitchen | kitchen_queue | queue_entry_time | order_id |
| Order Ready | kitchen_queue | completed_time | order_id |
| Assigned to Driver | delivery_assignments | assigned_at | order_id |
| Delivery Completed | delivery_assignments | delivered_at | order_id |
Separate direct events from inferred ones. A direct event has an explicit record and timestamp in a source system: Order Placed comes from the timestamp on the orders row, Payment Received from payments, Delivery Completed from delivery_assignments. These are usually straightforward to extract, provided the timestamp represents the event you want to analyze.
An inferred event has no record of its own, so you derive its timing from another field. Assigned to Driver may only exist as the creation time of the delivery assignment, and Order Ready may only be the moment the kitchen queue status changed to “completed.” Inferred events can be useful, but document how you derived them: a status change or a record creation time may not mean exactly what the activity label suggests, so check the field’s meaning with people who know the source system before treating it as an event timestamp.
This mapping is a plan, not proof that every field is suitable. Check whether timestamps are populated and whether each table can be joined to the order ID without creating duplicate rows.
Case and event attributes
Attributes add context to your analysis. They are the columns beyond Case ID, Timestamp and Activity, and they are worth adding only when they have a clear meaning and can be linked to the right case or event.
Case attributes describe the whole case and usually stay the same across its events: customer name, order total value, delivery address, number of items ordered. In a flat event log you repeat the value on every row for that case, which is what lets you filter or compare events using case-level information later.
Event attributes describe one event: the driver on a delivery event, the payment method on a payment event, the kitchen station on a kitchen event. A column like that does not apply to every row, so leave it blank where it does not apply, and keep the column in the table so every row keeps the same structure.
Your finished event log should be one flat table, with one event per row. Here is the Pizza Palace log:
| Case ID | Timestamp | Activity | Customer | Order Value | Driver | Payment Method |
|---|---|---|---|---|---|---|
| 1001 | 2025-01-15 18:30:00 | Order Placed | John Smith | 45.99 | ||
| 1001 | 2025-01-15 18:30:15 | Payment Received | John Smith | 45.99 | Credit Card | |
| 1001 | 2025-01-15 18:31:00 | Order Sent to Kitchen | John Smith | 45.99 | ||
| 1001 | 2025-01-15 18:45:00 | Order Ready | John Smith | 45.99 | ||
| 1001 | 2025-01-15 18:46:00 | Assigned to Driver | John Smith | 45.99 | Maria Garcia | |
| 1001 | 2025-01-15 19:05:00 | Delivery Completed | John Smith | 45.99 | Maria Garcia | |
| 1002 | 2025-01-15 18:35:00 | Order Placed | Jane Doe | 28.50 | ||
| 1002 | 2025-01-15 18:35:20 | Payment Received | Jane Doe | 28.50 | PayPal | |
| … | … | … | … | … | … | … |
The customer and order value repeat for each event in the same case. That repetition is intentional: it keeps the log in a simple table that process mining tools can read.
Method 1: build it in Excel
Excel works well for a small extract or a first exercise. Export each event type, standardize the columns, and combine the rows into one sheet. The five steps below take about an hour on the Pizza Palace data.
Step 1: export each event type to a separate sheet. Create a worksheet for each activity type. For example:
Sheet 1: Order Placed
| Case ID | Timestamp | Activity | Customer | Order Value |
|---|---|---|---|---|
| 1001 | 2025-01-15 18:30:00 | Order Placed | John Smith | 45.99 |
| 1002 | 2025-01-15 18:35:00 | Order Placed | Jane Doe | 28.50 |
Sheet 2: Payment Received
| Case ID | Timestamp | Activity | Customer | Order Value | Payment Method |
|---|---|---|---|---|---|
| 1001 | 2025-01-15 18:30:15 | Payment Received | John Smith | 45.99 | Credit Card |
| 1002 | 2025-01-15 18:35:20 | Payment Received | Jane Doe | 28.50 | PayPal |
Create additional sheets for kitchen and delivery events using the same approach.
Step 2: standardize the columns. Use the same column names in the same order on every sheet, and add blank columns where an attribute does not apply. The Order Placed sheet, for example, can carry the full set of columns:
| Case ID | Timestamp | Activity | Customer | Order Value | Driver | Payment Method |
|---|---|---|---|---|---|---|
| 1001 | 2025-01-15 18:30:00 | Order Placed | John Smith | 45.99 |
Check that the values use compatible formats. In particular, make sure timestamps are stored as dates and times rather than as text that only looks like a timestamp.
Step 3: combine the sheets. Create a new sheet called Event Log and copy the event rows from each activity sheet into it, keeping one header row and one event per row.
Step 4: sort by case and timestamp. Sort the combined data by Case ID ascending, then Timestamp ascending. This makes it easier to review each case’s sequence. Sorting does not correct inaccurate timestamps, so check events with identical or unexpected times before relying on their order.
Step 5: export to CSV. Save the combined sheet as a process mining event log CSV that your tool can read, and open the exported file once to confirm the headers, delimiters, date format and blank values look as expected.
Excel tips:
- Use VLOOKUP or XLOOKUP to add case attributes, such as customer name, from the orders sheet.
- Use one consistent date and time format, such as
YYYY-MM-DD HH:MM:SS. - Check for duplicate rows before exporting.
- Keep an unchanged copy of the original extracts so you can trace any corrections.
Method 2: build it with SQL
SQL is worth it when your data sits in a database, the extract is large, or you need to run the same extraction again next month. The usual shape is one SELECT per activity, stacked with UNION ALL.
How UNION ALL works. It stacks the rows returned by multiple SELECT statements. Each statement must return the same number of columns, in the same order, with compatible data types, and a consistent set of aliases so the final columns have clear names.
The query. The example below uses the fictional Pizza Palace tables. Check your own table names, field names, timestamp meanings and SQL dialect before adapting it.
-- Event Log Extraction for Pizza Palace
-- This query combines multiple event types into a single event log
-- Each SELECT block represents one activity type

-- Event 1: Order Placed
-- Source: orders table
-- This captures when customers submit their orders
SELECT
    o.id AS case_id,                          -- The order ID is our case identifier
    o.created_at AS timestamp,                -- When the order was placed
    'Order Placed' AS activity,               -- The activity name (hardcoded)
    o.customer_name AS customer,              -- Case attribute: who ordered
    o.total_amount AS order_value,            -- Case attribute: order value
    NULL AS driver,                           -- Not applicable for this event
    NULL AS payment_method                    -- Not applicable for this event
FROM orders o
WHERE o.created_at >= '2025-01-01'            -- Filter to your desired date range

UNION ALL

-- Event 2: Payment Received
-- Source: payments table
-- This captures successful payment processing
SELECT
    p.order_id AS case_id,
    p.payment_time AS timestamp,
    'Payment Received' AS activity,
    o.customer_name AS customer,              -- Join to get case attributes
    o.total_amount AS order_value,
    NULL AS driver,
    p.payment_method AS payment_method        -- Event-specific attribute
FROM payments p
JOIN orders o ON p.order_id = o.id            -- Join to get order details
WHERE p.payment_time >= '2025-01-01'
  AND p.status = 'successful'                 -- Only include successful payments

UNION ALL

-- Event 3: Order Sent to Kitchen
-- Source: kitchen_queue table
-- This captures when the kitchen starts working on the order
SELECT
    k.order_id AS case_id,
    k.queue_entry_time AS timestamp,
    'Order Sent to Kitchen' AS activity,
    o.customer_name AS customer,
    o.total_amount AS order_value,
    NULL AS driver,
    NULL AS payment_method
FROM kitchen_queue k
JOIN orders o ON k.order_id = o.id
WHERE k.queue_entry_time >= '2025-01-01'

UNION ALL

-- Event 4: Order Ready
-- Source: kitchen_queue table (different timestamp field)
-- This is an inferred event based on when the kitchen marked it complete
SELECT
    k.order_id AS case_id,
    k.completed_time AS timestamp,            -- Different timestamp than entry
    'Order Ready' AS activity,
    o.customer_name AS customer,
    o.total_amount AS order_value,
    NULL AS driver,
    NULL AS payment_method
FROM kitchen_queue k
JOIN orders o ON k.order_id = o.id
WHERE k.completed_time >= '2025-01-01'
  AND k.completed_time IS NOT NULL            -- Only include completed orders

UNION ALL

-- Event 5: Assigned to Driver
-- Source: delivery_assignments table
-- This captures when a driver is assigned to deliver the order
SELECT
    d.order_id AS case_id,
    d.assigned_at AS timestamp,
    'Assigned to Driver' AS activity,
    o.customer_name AS customer,
    o.total_amount AS order_value,
    d.driver_name AS driver,                  -- Event-specific attribute
    NULL AS payment_method
FROM delivery_assignments d
JOIN orders o ON d.order_id = o.id
WHERE d.assigned_at >= '2025-01-01'

UNION ALL

-- Event 6: Delivery Completed
-- Source: delivery_assignments table (different timestamp field)
-- This captures when the order was delivered to the customer
SELECT
    d.order_id AS case_id,
    d.delivered_at AS timestamp,
    'Delivery Completed' AS activity,
    o.customer_name AS customer,
    o.total_amount AS order_value,
    d.driver_name AS driver,
    NULL AS payment_method
FROM delivery_assignments d
JOIN orders o ON d.order_id = o.id
WHERE d.delivered_at >= '2025-01-01'
  AND d.delivered_at IS NOT NULL              -- Only include completed deliveries

-- Final ordering: by case, then by time
-- This makes the event log easy to read and follow
ORDER BY case_id, timestamp;
The query uses the order ID as the case ID and returns the same seven columns for each activity. The NULL values keep the column structure consistent when an attribute does not apply. The date filter and the successful-payment condition are examples: choose filters that match the process and period you want to analyze.
Extending the query. To add another activity:
- Copy a
SELECTblock as a starting point. - Use the source table that records the event.
- Select the field that represents its timestamp.
- Set an activity name that is consistent with your other rows.
- Include the case ID and any relevant attributes.
- Add filters that match your analysis.
For example, a delivery attempt could be added like this if your system has the relevant table and fields:
UNION ALL

-- Event 7: Delivery Attempted
-- Add this to track failed delivery attempts
SELECT
    d.order_id AS case_id,
    d.attempt_time AS timestamp,
    'Delivery Attempted' AS activity,
    o.customer_name AS customer,
    o.total_amount AS order_value,
    d.driver_name AS driver,
    NULL AS payment_method
FROM delivery_attempts d
JOIN orders o ON d.order_id = o.id
WHERE d.attempt_time >= '2025-01-01'
Checks before you analyze the log
Run these checks before you analyze the log. Together they cover the event log imperfection patterns for process mining that cause the most misleading results: duplicates, missing timestamps, unstable case IDs, and status fields mistaken for activities.
- Start with the required columns. Build a small log with Case ID, Timestamp, and Activity before adding more events or attributes.
- Use stable case IDs. Every event for the same case should use the same identifier. Do not use a value that changes during the process.
- Keep activity names consistent. Choose one label, such as “Order Placed,” rather than mixing it with “Order Created” and “New Order.”
- Check timestamps. Confirm they represent the event time, use a consistent time zone, and can be sorted as dates and times.
- Review duplicates and missing values. Investigate repeated events and rows with a missing case ID, timestamp, or activity.
- Document your extraction. Record the source tables, fields, filters, extraction date, and assumptions. This makes the log easier to update and troubleshoot.
- Add attributes with care. Include fields that help answer a question, and confirm that joins do not multiply event rows.
Seven common data problems, from duplicate events to missing case IDs, have their own answers in the FAQ at the end of this page, and ETL for process mining covers the recurring-extraction version of the same work.
What to do when you do not have the data
You do not need a prebuilt connector to prepare an event log. Start by checking what your system can export and whether it gives you the three required fields.
- Identify the process and the case ID you want to follow.
- Check whether the system can export event history, audit records, or timestamped status changes.
- Use a data template to map the available fields to Case ID, Timestamp, and Activity.
- If you cannot export a ready-made event table, ask your data team for a database extract or a report with one row per event.
A system export may contain several tables or use different names for the same field. You can combine and rename the data in Excel or SQL, as long as you preserve each field’s meaning and can trace it back to its source. Where to get process mining data covers the other places usable source data hides, and the process improvement guides have already done steps 1 to 3 for your system, with a data template per process.
If you want another process mining event log example to compare formats, the example log files and templates collection includes a ready-made spreadsheet, and the template event log page lists the required and optional columns. For a walkthrough of the first dataset, see load your first dataset.
Load the log you built
When the log is ready, load the file and map its three required columns. ProcessMind reads Excel, CSV, and database extracts directly.
- Upload your file or select your database extract.
- Map the Case ID, Timestamp, and Activity columns.
- Review any additional attributes.
- Generate the process view and check that the cases and event order make sense.
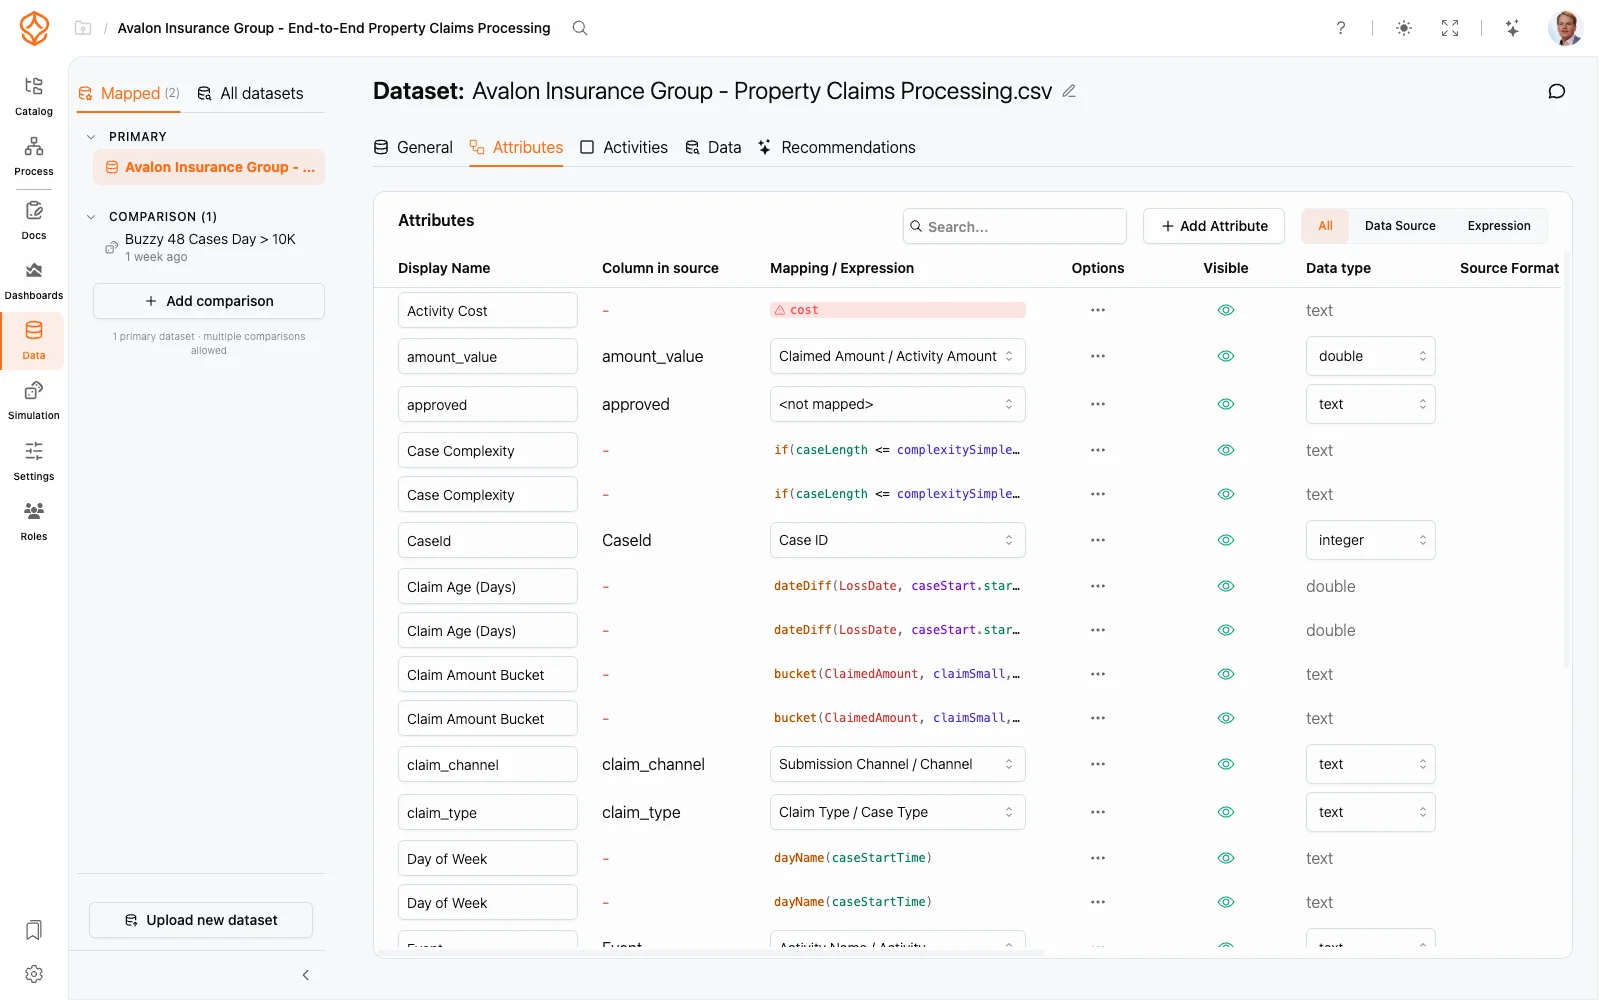
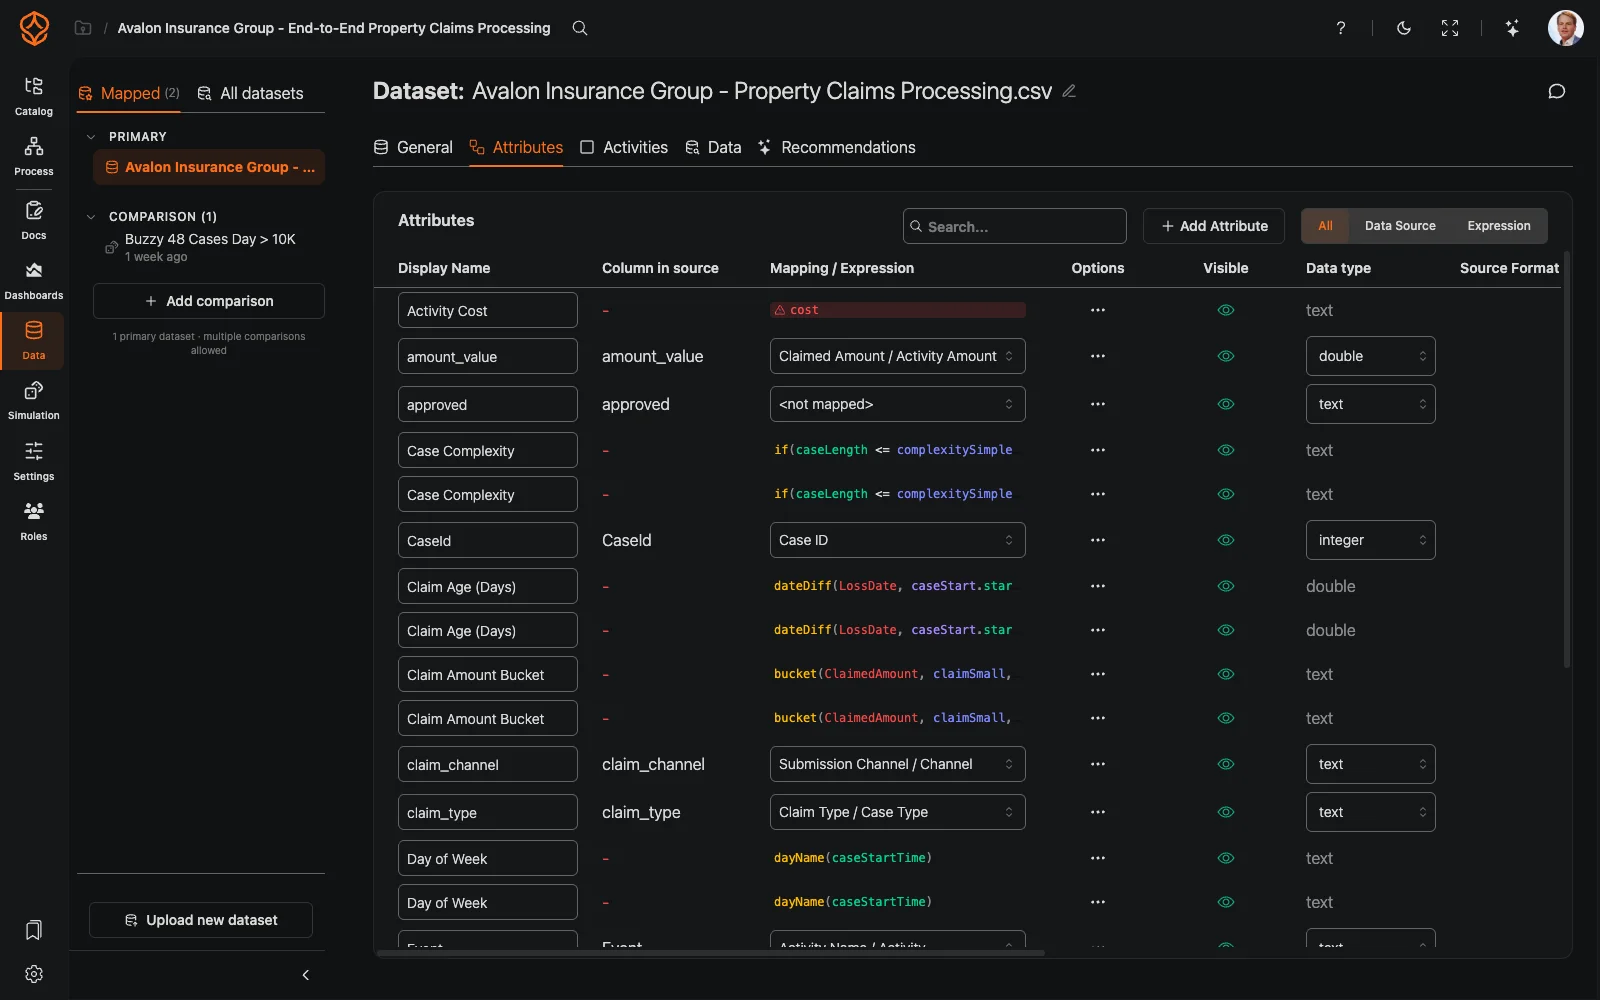
A process view can help you spot missing activities, unexpected sequences, and areas to investigate. It does not fix the source data or change how work is performed, so if the first result exposes a data issue, update the extract and load it again. Load your first dataset walks through the upload and the mapping in detail.
Where to Go From Here
You have an event log, or the three columns you need for one, and the next step is seeing what the process actually does.